All projects
Natural Language Processing
NLP from first principles
A single notebook covering four small language systems, built on the Stanford Sentiment Treebank and on literary texts.
- Context
- UCL Natural Language Processing, individual coursework
- Date
- March 2026
- Team
- Individual
- Stack
- Python, NumPy, pandas, scikit-learn, PyTorch, Hugging Face Transformers
What it covers
Sentiment with logistic regression
Tokenisation, hand-built features and word embeddings, compared on the same task.
A neural sentiment classifier
An MLP in PyTorch with hyperparameter tuning, compared against zero-shot and few-shot classification by large language models.
Information retrieval
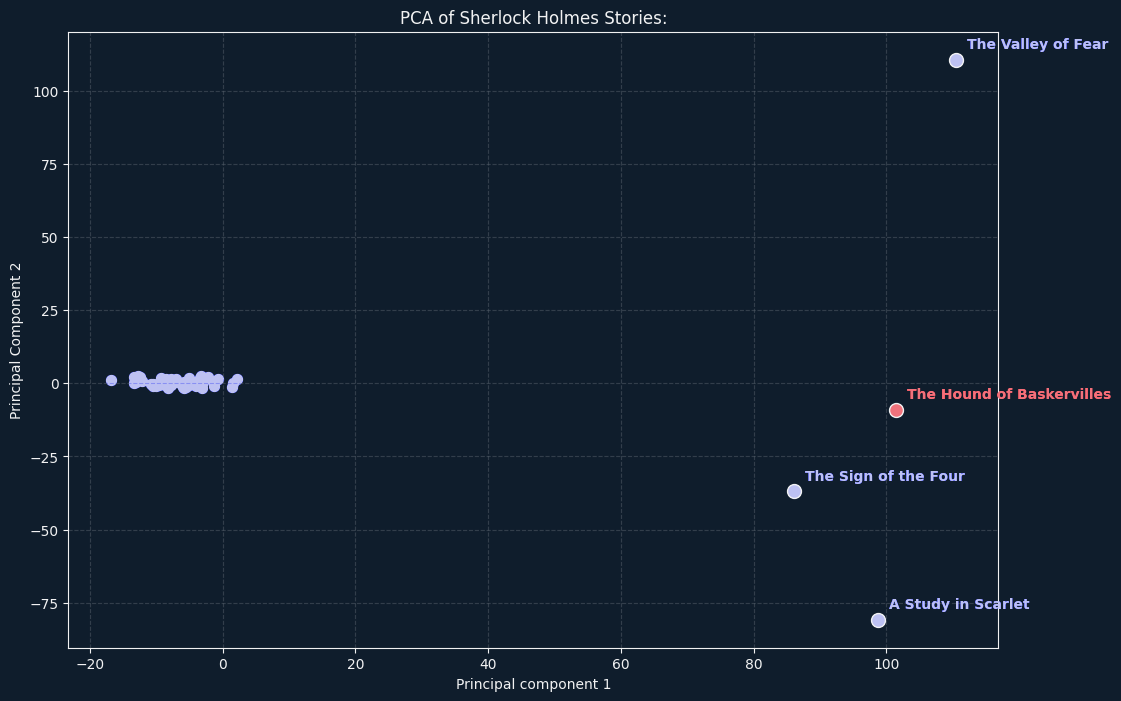
Preprocessing, named entity recognition, TF-IDF vectors and cosine similarity to retrieve documents from the Sherlock Holmes stories, with a two-dimensional projection of the document vectors.
Text generation
Unigram, bigram and longer n-gram language models, written without libraries.