Natural Language Processing, team of five
Sentiment by product category
A group project asking whether sentiment models are as good at spotting negative reviews in one product category as in another.
- Context
- UCL Natural Language Processing, group proposal and final project
- Dates
- February to March 2026
- Team
- Five
- Stack
- Python, Hugging Face, scikit-learn, BERT, RoBERTa
The question
A single accuracy figure can hide weak performance in particular categories. A review of a technical electronics product is written very differently from a review of clothing. We proposed evaluating models category by category instead.
My part
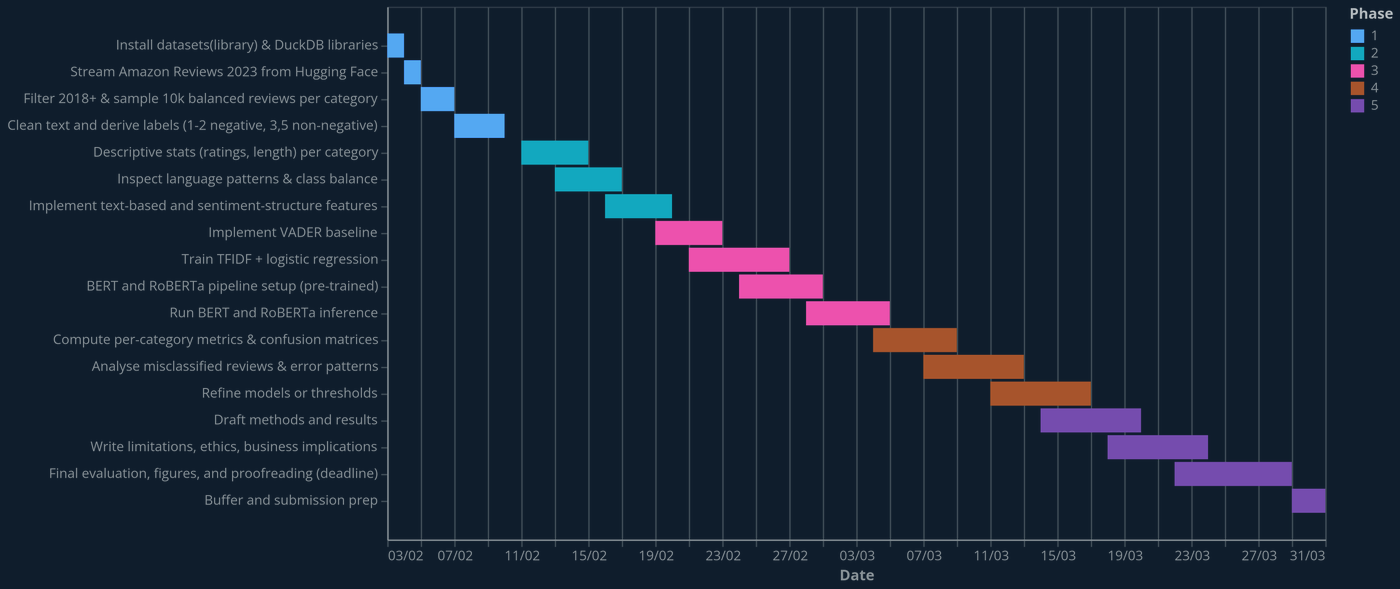
In the proposal I worked on framing that gap, the literature review across lexicon-based, classical and transformer methods, the methodology and dataset, and the plan and task split shown below.
In the final project I worked on the data preparation for the Amazon Reviews data. We compared a classical model (TF-IDF with logistic regression) against BERT-family transformers, broke the results down by category, and ran topic modelling on the negative reviews the models got wrong to see what customers were complaining about. I co-presented the findings in the recorded presentation.